I have thrown away more LoRAs because of the dataset than because of learning-rate mistakes. The training log looked healthy. The loss curve behaved. The first grid looked promising. Then the model started inserting the same chair, the same window light, or the same three-quarter head angle into every new prompt. The culprit was almost never the trainer. It was five quiet dataset problems that do not announce themselves until the adapter is already in production.
This Failure File walks through each problem the way I now hunt for it—before any training run starts.
Problem 1: Hidden Pose and Crop Bias
If 80 % of your images show the subject from the same three-quarter angle and the same crop, the LoRA will treat that angle as part of the identity. Later, when a client asks for a pure profile or a full-body shot, the face collapses or the body proportions invent themselves.
I now force a simple count before training:
Front / three-quarter / profile distribution
Close-up / medium / full-body distribution
Standing / seated / action distribution
Any cell under 15 % gets more images or the set is rejected.
Problem 2: Lighting That Became a Feature
Soft window light on the left side of every training image teaches the model that “correct” skin looks like that specific fall-off. Hard sunlight or overhead fluorescent then produces plastic or muddy skin. The fix is deliberate lighting variety, not more images of the same soft key.
Problem 3: Backgrounds That Leak into the Subject
A distinctive background object that appears in many frames becomes a latent co-trigger. I once had a plant that kept reappearing next to every character even when the prompt said “plain studio.” Cropping tighter or masking the background before training is cheaper than trying to negative-prompt the plant forever.
Problem 4: Caption Drift and Over-Captioning
When captions describe every clothing fold and every prop, the LoRA learns those details as strongly as the face. Later the model ignores the prompt’s wardrobe block because the training captions already locked the outfit. I keep captions short and identity-focused: age, face traits, hair, one marker. Wardrobe and scene belong in the inference prompt, not the training text.
Problem 5: Near-Duplicates That Inflate Apparent Size
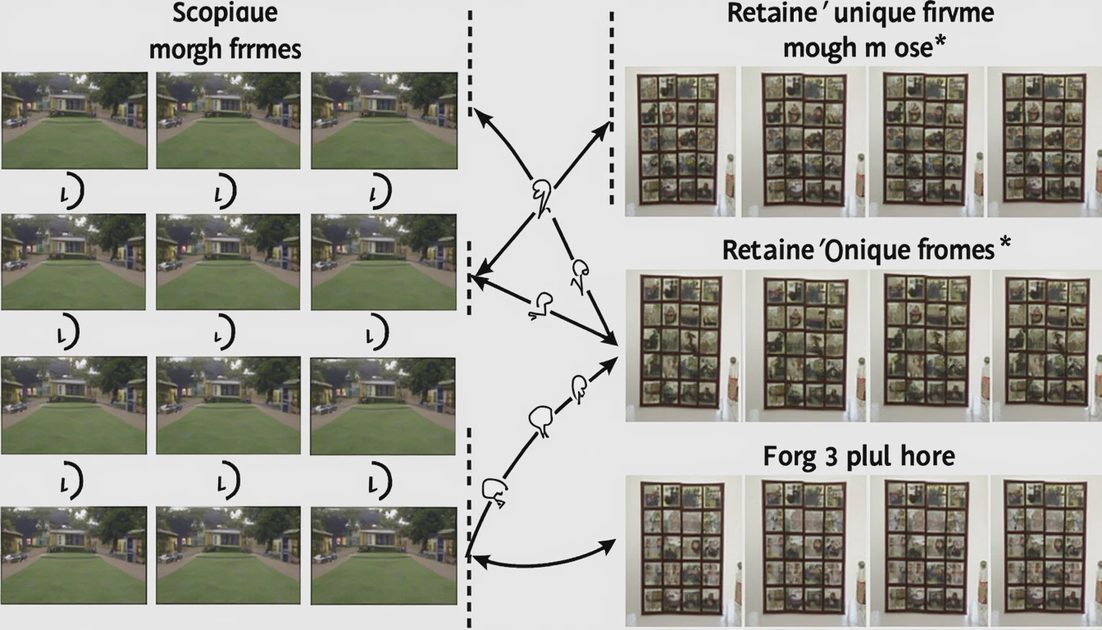
Fifty images that are essentially the same frame with slight crop shifts count as one image in the model’s eyes. They inflate the reported dataset size and give false confidence. I now run a perceptual-hash pass and drop anything above a similarity threshold. The real unique count is what matters.
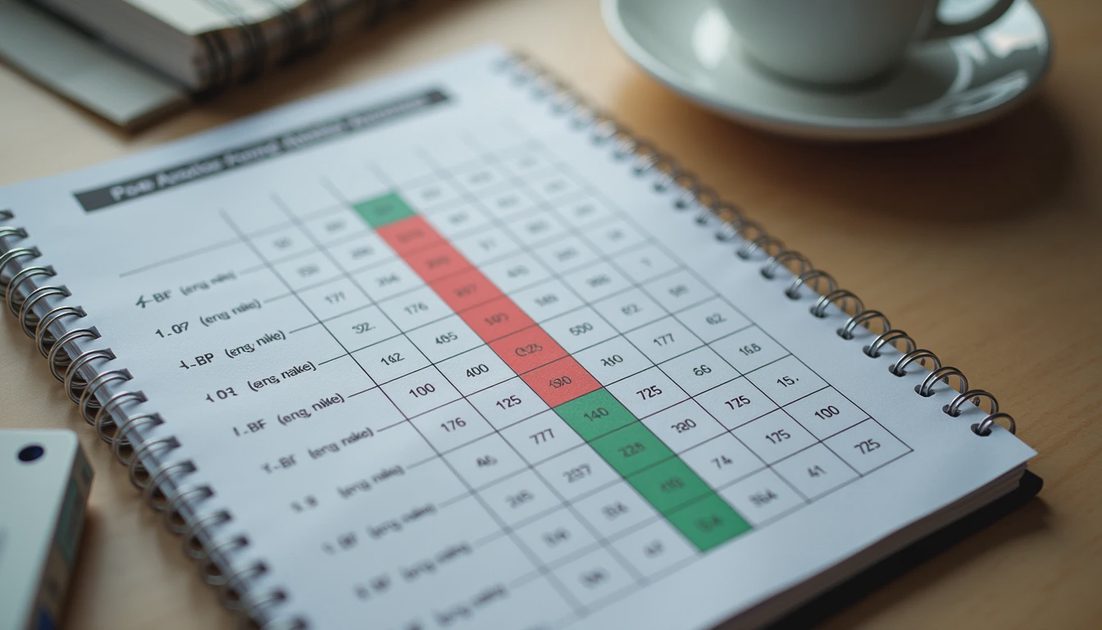
Problem | Early warning sign | Quick diagnostic | Recovery cost |
|---|---|---|---|
Pose/crop bias | Profile or full-body fails | Count distribution table | Medium – add images |
Lighting lock | Skin tone collapses under new light | Side-by-side lighting test | Medium – re-shoot or re-light |
Background leak | Props reappear unprompted | Generate plain-background probes | Low – crop or mask |
Caption drift | Prompt wardrobe ignored | Compare short vs. long captions | Low – rewrite captions |
Near-duplicates | Dataset feels larger than results | Perceptual hash filter | Low – delete duplicates |
The Pre-Training Dataset Audit I Actually Run
Before any training job leaves the queue I spend twenty minutes on this checklist:
Unique image count after hash filtering
Pose and crop distribution table
Lighting variety check (at least three distinct keys)
Background object audit
Caption length and focus review
Identity-card compliance on every kept image
If any item fails, the set goes back to the source, not into the trainer. That single gate has prevented more wasted GPU hours than any learning-rate scheduler I have tried.
What a Clean Starter Set Looks Like in Practice
For a character LoRA I aim for 25–40 truly unique images that already satisfy the identity card under varied but controlled conditions. More images only help if they add new information. Repeating the same information at higher resolution does not.
I keep a simple distribution table next to the folder: number of unique poses, number of distinct lighting keys, number of background classes, and the percentage of images that would fail the identity card on a cold read. If any column is empty or dominated by a single value, the set is not ready. That table takes five minutes to fill and has saved me from more than one overnight training run that would have produced a beautiful but useless adapter.
A Failure Story That Started With “Almost Clean”
One recent set looked excellent on first pass—no near-duplicates, balanced crops, varied lighting. The captions, however, all mentioned the same outdoor location name. The finished LoRA could not generate the character indoors without inventing trees or sky. The background leakage was invisible until the first out-of-distribution prompt. After that I added an explicit “background object audit” step that forces me to list every recurring non-character element. The extra five minutes of work is cheaper than another training cycle.
Why Metrics Alone Will Not Catch These Problems
Training loss curves and sample grids generated from the training distribution almost never surface pose bias or caption drift. The model is rewarded for reproducing what it saw. Only prompts that deliberately step outside the training distribution reveal the hidden constraints. That is why the pre-training audit is human-driven and why every finished LoRA still faces a separate out-of-distribution probe set. Run the test. Save the settings. Show the failure. The dataset is the first place most LoRAs actually break.
No comments yet.